Integration with Neuron
Neuron is an industrial IoT connectivity platform developed by EMQ. It supports industrial protocols such as Modbus, OPC UA, and BACnet. eKuiper is an open-source, lightweight edge stream processing engine. It processes data with SQL and forwards results through output actions called sinks. NeuronEX is EMQ's industrial edge data collection and processing software. It combines Neuron's protocol connectivity with eKuiper's stream processing and provides a unified web interface for configuring data collection, processing, and forwarding.
This guide describes three ways to write data collected by Neuron to TDengine:
- Install-time onboarding: For environments where NeuronEX Enterprise is not yet installed. The installation command installs NeuronEX, registers it with taosExplorer, creates the
neuronbusiness database, theneuron_demodemo database, and four demo devices, and configures the write path. No operation in taosExplorer is required after installation. - One-click onboarding: For environments where Neuron or NeuronEX is already deployed. On the Data In → Data Collection Agents → Neuron page in taosExplorer, enter the Neuron address and credentials; taosExplorer automatically configures the data stream, processing rules, and collection subscriptions.
- Manual onboarding: For environments where Neuron or NeuronEX is already deployed and you need custom tags, business attributes, or data transformation. Manually configure the data stream, processing rule, and InfluxDB v1 write action in the NeuronEX interface.
| Method | Neuron preinstalled? | Use case | taosExplorer operation |
|---|---|---|---|
| Install-time onboarding | No | NeuronEX Enterprise not yet installed | None |
| One-click onboarding | Yes | Neuron or NeuronEX already deployed | Wizard |
| Manual onboarding | Yes | Already deployed; custom tags or transformation needed | Manual configuration |
All three methods share the same data plane: Neuron sends collection reports to eKuiper; eKuiper extracts measurement columns and tags, encodes them as Influx line protocol, and writes them to TDengine in batches; schemaless writes automatically create the supertable and subtables. This integration can ingest data from the more than 70 industrial protocols supported by Neuron, subject to the version and license.

Neuron and TDengine integration architecture
As shown above, Neuron converts device data into JSON collection reports; eKuiper extracts measurement columns and tags, encodes them as Influx line protocol, and writes them to TDengine in batches; schemaless writes automatically create the supertable and subtables. To use mutual TLS (mTLS) or high availability, see Encrypted Transport and High Availability.
Prerequisites
Preparing Neuron and eKuiper
Not installed
- Use the
apextool provided by the TDengine Enterprise installation package. - You do not need to install Neuron or eKuiper beforehand: the installation automatically installs NeuronEX (which bundles eKuiper) and registers it with taosExplorer.
- Same-host installation requires no additional network configuration. For cross-host installation, the NeuronEX host must be able to reach ports
6041(taosAdapter) and6060(taosExplorer) on the TDengine host, and taosExplorer must be able to reach port8085(management) on the NeuronEX host. - The installation automatically creates the business database
neuron(--database), the demo databaseneuron_demo(--database-demo), four demo devices (collection groupmeters), and demo rules. After installation, you can view the result directly in taosExplorer. To connect real devices, continue adding devices, collection groups, and tags in NeuronEX.
Already installed
- Neuron and eKuiper are deployed: either NeuronEX 4.0.0 or later (which bundles both; see Install NeuronEX), or the open-source combination of Neuron 2.15.0 or later and eKuiper (which must include the InfluxDB v1 sink).
- Device collection is configured in Neuron (or NeuronEX): devices are added, collection groups are created, and tags are configured; devices are running and connected, and tag values are continuously updating in Data Monitoring. Any protocol supported by Neuron can be used — Modbus, OPC UA, Siemens S7, and so on.
- The Neuron host can reach the taosAdapter HTTP port, which is
6041by default. - A database for writing has been created. One-click onboarding does not create a database automatically; the manual onboarding example creates a demo database.
- After installation and collection configuration, choose One-Click Onboarding or Manual Onboarding.
General
- TDengine TSDB 3.4.3.6 or later.
- To buffer data during outages and resend after recovery, confirm that eKuiper includes the retry fix described in Store and Forward.
Install-Time Onboarding
Install-time onboarding relies on the apex tool, which is not yet released. It is planned for release in early November 2026. Stay tuned.
This section applies to environments where NeuronEX Enterprise is not yet installed. The installation automatically creates the business database neuron, the demo database neuron_demo, four demo devices, and the collection group meters. After installation, you can view the result directly in taosExplorer without creating an integration there. To connect real devices, continue adding devices, collection groups, and tags in NeuronEX. Before configuring devices, review the Data Mapping and Collection Configuration Guidelines.
The installation command is provided by the apex tool in the TDengine Enterprise package; you do not need to install NeuronEX separately.
After installation, taosExplorer polls the NeuronEX device list every 5 minutes by default. When it finds a new device with configured tags, it automatically creates or updates the integration rules without any action in taosExplorer. Automatic discovery only covers new device names; when an existing device adds a collection group or tags, click Refresh Configuration on the taosExplorer detail page to rescan. Adjust the polling interval with the taosExplorer environment variable NEURON_POLL_INTERVAL_SECS (default 300 seconds); set it to 0 to disable polling.
taosExplorer manages the rules and subscriptions it creates. Do not edit generated rules in eKuiper: a refresh reconciles an owned rule to the current mapping and overwrites manual changes. Configure devices, groups, and tags in Neuron or NeuronEX, then use Refresh Configuration.
For same-host installation, no connection parameters are required. For cross-host installation, you must specify the TDengine host address. For other parameters, see Cross-Host Installation.
Same-Host Installation
When TDengine and NeuronEX are deployed on the same host, run:
sudo apex install all
The installation automatically performs the following work:
- Install and start NeuronEX; the default web port is
8085. - Register NeuronEX with the local taosExplorer.
- Create the business database
neuron(--database, defaultneuron); reuse it if it already exists. - Create the demo database
neuron_demo(--database-demo, defaultneuron_demo); reuse it if it already exists. - Create four Modbus simulator devices,
demo_meter01throughdemo_meter04, all in themeterscollection group and writing toneuron_demo. - Configure TDengine write parameters and generate demo rules with a
locationtag. - Generate a NeuronEX administrator password and save it to
/var/lib/apex/neuronex-admin-password(readable only by root).
After installation, NeuronEX is connected to the local TDengine; you do not need to enter a Neuron address, database, or integration configuration. Typical output:
[apex] Installing TDengine All-in-One...
[apex] NeuronEX installed and started: http://127.0.0.1:8085
[apex] NeuronEX registered with taosExplorer: http://127.0.0.1:6060
[apex] Database neuron created.
[apex] Demo database neuron_demo created.
[apex] Demo devices created: demo_meter01, demo_meter02, demo_meter03, demo_meter04
[apex] NeuronEX admin password saved to /var/lib/apex/neuronex-admin-password
[apex] NeuronEX is connected to TDengine.
Cross-Host Installation
When TDengine is on another host, run the following on the NeuronEX host:
sudo apex install neuronex --tdengine-host 192.168.1.100
Replace 192.168.1.100 with the IP address or domain name of the target TDengine host. Other parameters use their defaults. To customize the TDengine username, password, or other settings, append the parameters in the following table:
| Parameter | Default | Description |
|---|---|---|
--tdengine-host | Local host | TDengine host IP or domain name; required for cross-host installation |
--tdengine-port | 6041 | taosAdapter REST port |
--tdengine-user | root | TDengine username; must have permission to create databases and write to the target database |
--tdengine-password | taosdata | TDengine user password |
--explorer-port | 6060 | taosExplorer port |
--database | neuron | Business database; created automatically if it does not exist |
--database-demo | neuron_demo | Demo database; created automatically if it does not exist; the four demo devices write to it |
Cross-host installation also creates the business database neuron, the demo database neuron_demo, and four demo devices. After installation, NeuronEX registers with the taosExplorer automatically and configures the write path. The output is similar to same-host installation, with the registration address http://<TDengine_IP>:6060 and the TDengine target http://<TDengine_IP>:6041. If TDengine is already installed separately on the same host, you can omit --tdengine-host.
The installation generates a NeuronEX administrator password and saves it to /var/lib/apex/neuronex-admin-password. Use it when you log in to NeuronEX for the first time or add real devices:
sudo cat /var/lib/apex/neuronex-admin-password
To use a custom password, append --neuron-password-file <path> to the installation command.
View the Result in taosExplorer
Both same-host and cross-host installation automatically create an integration record in taosExplorer. Log in to taosExplorer and go to Data In → Data Collection Agents → Neuron to see the automatically created NeuronEX integration. The demo devices write data every second, and the status changes to Verified automatically. In the neuron_demo database, you can see the meters supertable and four subtables, demo_meter01 through demo_meter04, with location tags Factory01.Workshop01, Factory01.Workshop02, Factory02.Workshop01, and Factory02.Workshop02. This page is for viewing only; you do not need to create an integration or enter any configuration.
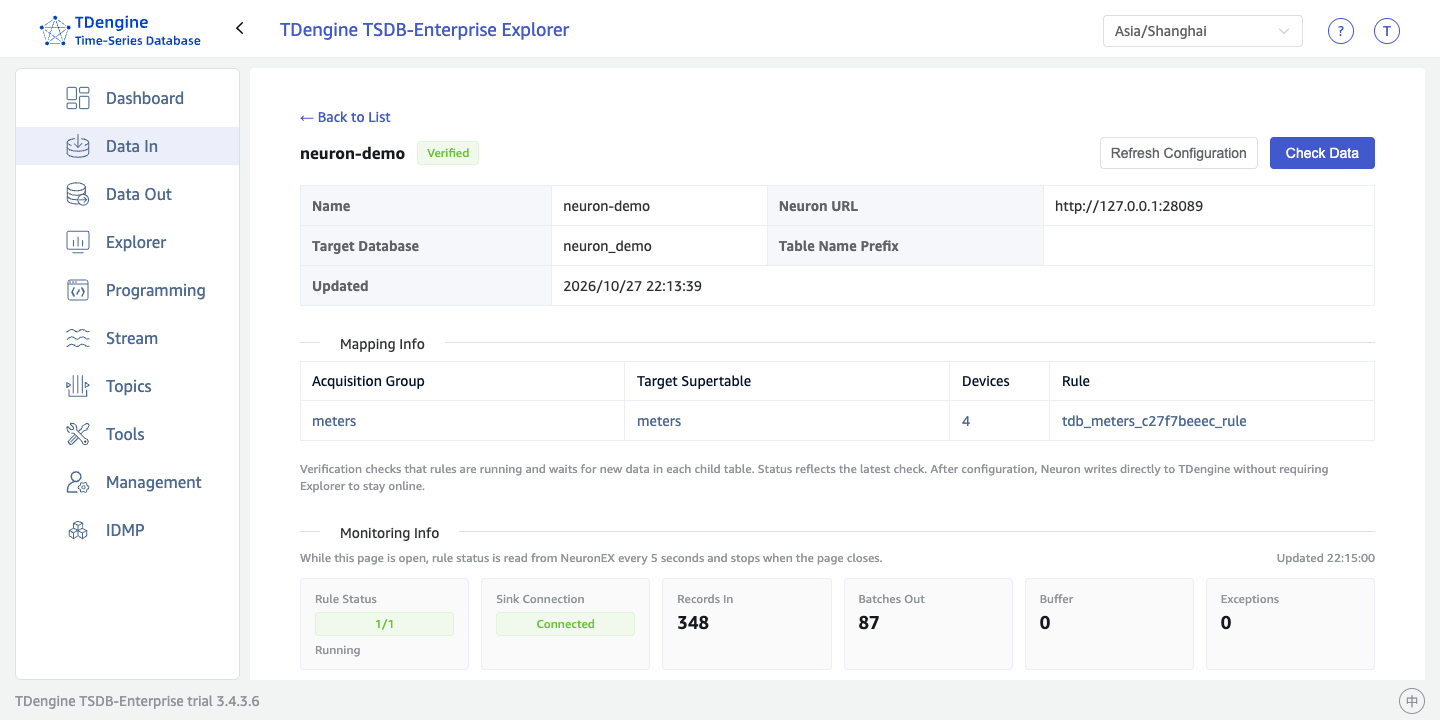
NeuronEX integration created automatically in taosExplorer
For ingestion verification, see Verify the Results.
One-Click Onboarding
This section applies to an environment where Neuron or NeuronEX is already deployed. For a fresh NeuronEX installation, use Install-Time Onboarding above.
One-click onboarding is completed in taosExplorer. You do not need to manually create data streams, rules, or subscriptions in NeuronEX or eKuiper; device collection must still be configured in advance. For general guidance on device naming, object mapping, and type mapping, see Data Mapping and Collection Configuration Guidelines.
1. Open the Onboarding Wizard
Log in to taosExplorer, select Data In in the left navigation, switch to the Data Collection Agents tab, and click the Neuron card.
2. Enter Connection Information
The upper part of the page is the Neuron connection information:
| Setting | Description |
|---|---|
| Name | Optional. Shown in the list and detail pages; the Neuron address is used when empty |
| Neuron URL | The Neuron management API address; the default is 8085 for NeuronEX and 7000 for open-source Neuron, for example http://neuron-host:8085 |
| Neuron Username / Neuron Password | The Neuron login credentials |
| eKuiper Port | Required for open-source Neuron only: the management port of eKuiper deployed on the Neuron host, default 9081. NeuronEX discovers its built-in eKuiper automatically, so this setting is not needed |
Below the divider is the TDengine write information:
| Setting | Description |
|---|---|
| TDengine Address | The REST address of taosAdapter in the current cluster (default port 6041). The Neuron gateway must be able to reach this address — use a hostname or IP reachable from Neuron, not a loopback address |
| Target Database | Select a database in the current cluster; the database must be created beforehand. Supertables and subtables are created automatically by schemaless writes — do not create them manually. A manually created table whose column types do not match the incoming data will fail the writes |
Click Next when finished. If the connection or validation fails, you stay on this page and the error is shown; fix the issue as prompted and try again.
3. Confirm the Mapping
The left side of the page lists the device count and target supertable for each collection group. The supertable name defaults to the collection group name and can be changed individually; groups with the same name share one mapping. When multiple Neuron gateways write to the same database with duplicate device names, set a distinct prefix for each gateway in Table Name Prefix. Click Preview Mapping to review the measurement columns of each group and the subtable each device writes to on the right (up to 10 devices per group), or click Next directly. For mapping rules and naming requirements, see Data Mapping and Collection Configuration Guidelines.
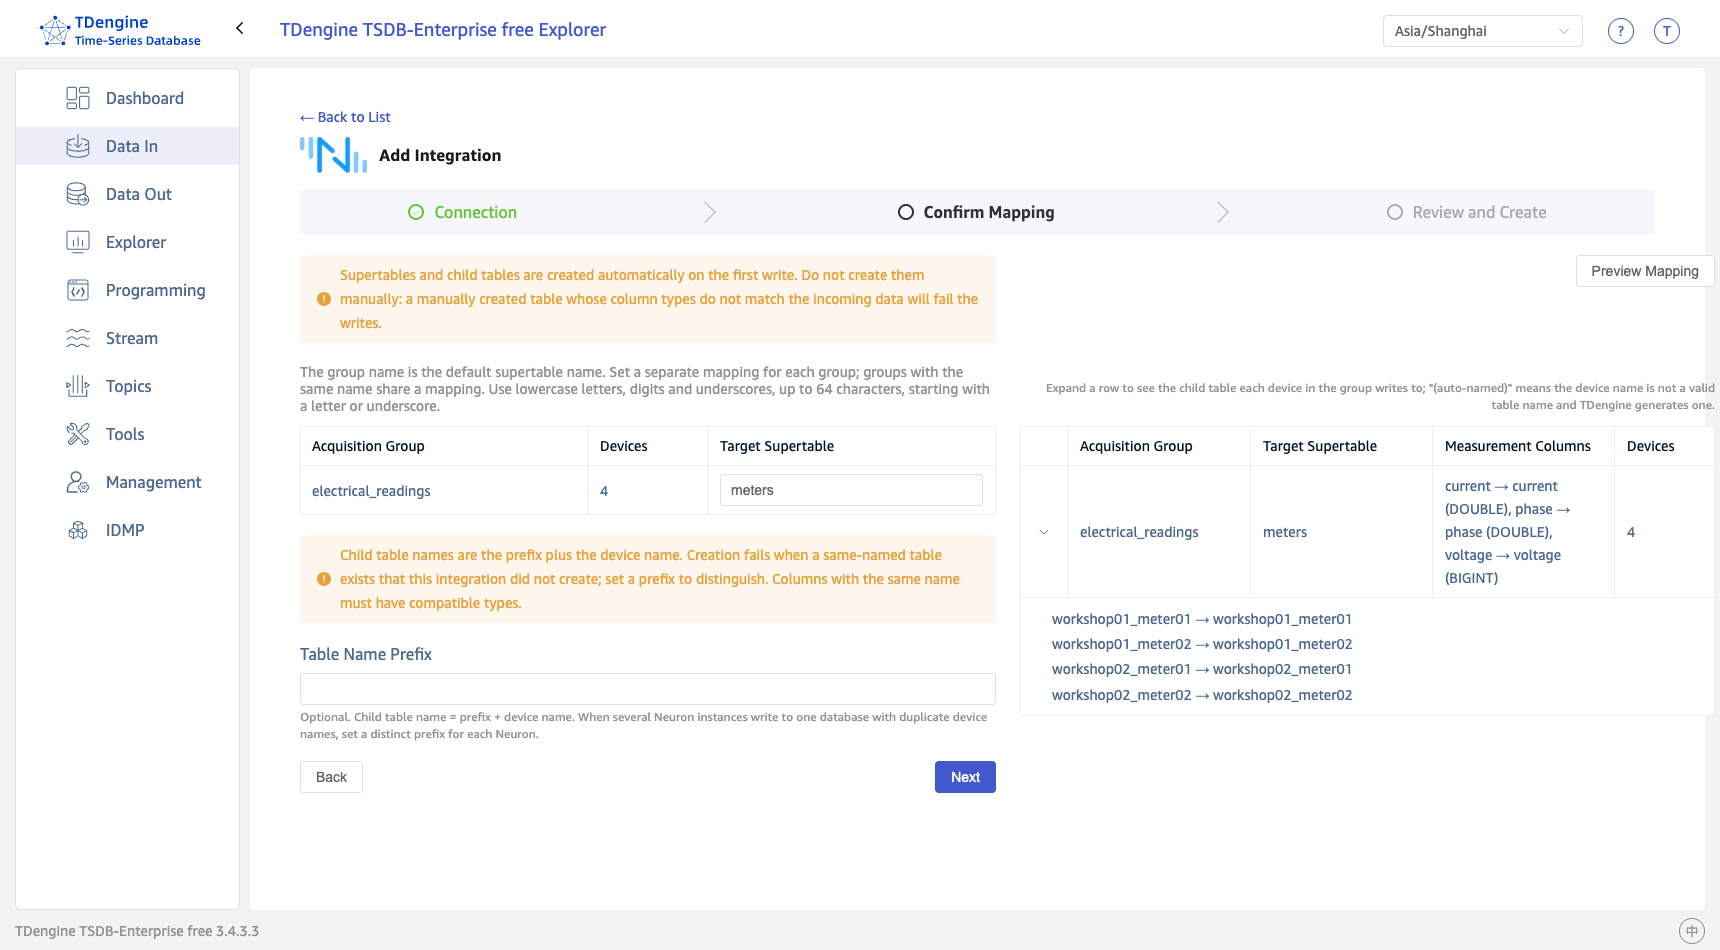
Confirming collection group and column mappings
4. Review and Create
The confirmation page summarizes the configuration to be created: Neuron address, eKuiper stream, TDengine address, target database, subtable naming rule, fixed tags, and write account. Review it and click Create Integration.
taosExplorer automatically performs the following:
- Creates or reuses the shared eKuiper stream (one stream is shared by all Neuron integrations);
- Creates an InfluxDB v1 write rule for each collection group, with the sink cache enabled and batching at 1,000 rows or 100 ms;
- Adds missing collection subscriptions (Neuron northbound subscriptions), leaving existing subscriptions unchanged;
- Checks subtable naming conflicts and refuses to create the integration with an explanatory message when a same-named subtable belongs to someone else.
Existing eKuiper configuration is never overwritten or deleted automatically. Rules write data using your current TDengine login account; after changing that account's password, click Refresh Configuration on the detail page to update the rules.
5. Check Status and Logs
After creation, the detail page opens: the upper part shows integration information, mapping information, and monitoring information, and the Execution Log panel below shows the latest 10 configuration and verification records, newest first.
A status of Verified means the rules are running and new data keeps appearing in every subtable. Other statuses: Configuring/Verifying means a background task is running; Configuration Preserved; Verification Pending means the configuration has been delivered but new data has not been observed yet; Failed/Interrupted — check the logs for the cause and retry.
The detail page provides two actions:
- Refresh Configuration: Re-delivers the stream and rules with the original configuration. Use it to recover after changing the TDengine password or after the rules are modified or deleted on the eKuiper side.
- Check Data: Runs data verification again to check whether each subtable has new data.
After configuration, data is written by Neuron through eKuiper directly to TDengine and does not depend on taosExplorer staying online; closing the taosExplorer page does not affect collection.
Manual Onboarding
This section applies to an existing Neuron or NeuronEX deployment where you need custom tags, business attributes, or data transformation. For a fresh NeuronEX installation, use Install-Time Onboarding above.
This section demonstrates the complete manual onboarding process in the NeuronEX interface using four Modbus TCP power meters as an example, for users who need custom tags, business attributes, or data transformation. The meters are only an example — you can follow the same procedure with other devices: replace step 3 with the collection configuration for your own device (select the appropriate protocol plugin, create a collection group, and add tags). The remaining steps (creating the database, stream, processing rule, and write action) are independent of the device type and are performed identically.
Example Data Model
For general object mapping, naming and grouping, and type mapping, see Data Mapping and Collection Configuration Guidelines; this example shows one concrete configuration.
This example uses two power meters in each of two workshops at one factory. Each meter reports current, voltage, and phase once per second. All four devices share the meters supertable and write to separate subtables. Each device uses a collection group named electrical_readings.
Device name, subtable name, and device tag | group_id | location |
|---|---|---|
workshop01_meter01 | 1 | Factory01.Workshop01 |
workshop01_meter02 | 1 | Factory01.Workshop01 |
workshop02_meter01 | 2 | Factory01.Workshop02 |
workshop02_meter02 | 2 | Factory01.Workshop02 |
TDengine stores Factory01.Workshop01 as the complete location tag value. IDMP can later split the value at the period into the hierarchy Factory01 → Workshop01.
The business fields follow the meters data modeling example. The first schemaless write automatically creates the tables with the following types:
| Category | Fields | Automatically generated type |
|---|---|---|
| Timestamp column | _ts | TIMESTAMP |
| Measurement columns | current, phase | DOUBLE |
| Measurement column | voltage | BIGINT |
| Tags | location, group_id, device | NCHAR |
The Influx line protocol encoding determines the actual field types, which differ from the standard meters example. Tag values containing only ASCII characters still produce NCHAR columns.
Data Mapping in This Example
In NeuronEX, first add the meter devices and configure their connections, then create a collection group and set its collection interval, and finally add tags such as current, voltage, and phase, specifying a register address and data type for each tag. Collection data maps to TDengine as follows:
| Neuron data | TDengine object | Configuration |
|---|---|---|
Device name, node_name | Subtable name and device TAG | The rule outputs device; the sink maps it to both tbname and the device tag |
Collection group name, group_name | Filters reports entering the rule | SQL selects the electrical_readings group; the sink's measurement setting independently specifies the supertable name |
Tags values.current, values.voltage, and values.phase | Measurement columns current, voltage, and phase | SQL extracts the tags; the sink's fields setting selects the columns to write |
Report timestamp, timestamp | Timestamp column _ts | SQL outputs ets; the sink sets tsFieldName=ets and precision=ms |
| Location and business group | TAGs location and group_id | SQL assigns attributes based on the device name; the sink's tags setting selects the tags |
In this example, each complete collection report from a meter becomes one row in its corresponding subtable. Current, voltage, and phase map to three measurement columns.
A Neuron tag is a collection point and maps to a measurement column. A TDengine TAG is a subtable attribute. group_id is a business group identifier configured separately from the collection group name. You can also map group_name to a TAG, but the group name must remain fixed for a given subtable.
Configuration Procedure
1. Create a Database
Run the following statement in a TDengine SQL client. Do not manually create the supertable or subtables.
CREATE DATABASE IF NOT EXISTS neuron_meters_demo PRECISION 'ms';
2. Check the Direct Connection Endpoint
Run the following command on the NeuronEX host or inside its container. Replace adapter-host with the actual taosAdapter hostname or IP address.
curl -i http://adapter-host:6041/influxdb/v1/ping
A 204 No Content response indicates that the endpoint is reachable. The InfluxDB v1 client calls this endpoint at startup. If it returns 404, check the path and confirm that TDengine is version 3.4.3.6 or later. NeuronEX can connect directly to taosAdapter without nginx. For encrypted transport or taosAdapter failover, configure nginx as described in Encrypted Transport and High Availability.
3. Configure Modbus Collection
-
Go to Data Collection → South Devices. Add four Modbus TCP devices with the example names and configure their connections.
Setting Value Purpose Connection mode Client Initiates a connection to the meter IP address and port Actual meter IP address and port, typically 502Identifies the device to read Connection timeout 3000msLimits the wait for an unresponsive request Command send interval 20msSets the interval between requests on the same connection; separate from the collection interval 32-bit byte order Follow the device manual, for example ABCDDecodes floating-point values correctly -
Create an
electrical_readingscollection group under each device. Set the interval to1000msand add the following three read tags.Tag name Type Example address Registers used currentFLOAT1!400001400001, 400002 voltageUINT161!400003400003 phaseFLOAT1!400004400004, 400005 Use the addresses specified in the device register map.
1!specifies unit ID 1. AFLOAToccupies two registers, so tag addresses must not overlap. Different device nodes can use the same register addresses.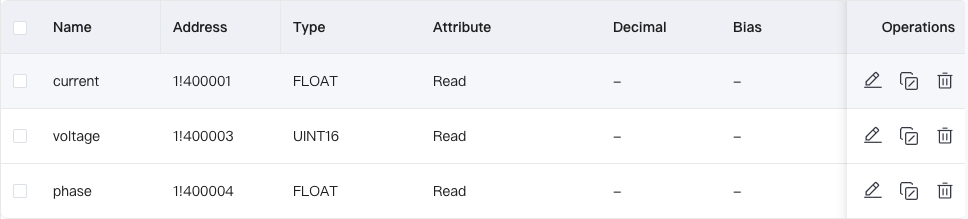
-
Save and start the devices. Confirm that each device is running and connected. In Data Collection → Data Monitoring, select each device and collection group, then verify that all three values are correct and continue to update.
-
Go to Data Collection → North Apps. Subscribe the built-in
DataProcessingapplication to theelectrical_readingsgroup on all four devices to send reports to eKuiper. Creating devices and a rule does not automatically create this subscription.
4. Create a Data Stream
A stream defines the field structure of collection reports. Rules read data from this stream.
-
Go to Data Processing → Sources → Create Stream and enter the following settings.
Setting Value Name meters_streamSource type NeuronConfiguration Key defaultStream Format JSONWhether the schema stream Enabled Shared True -
Add the following fields. Set
valuestoSTRUCTand add the three measurement fields beneath it.Field Type Purpose timestampBIGINTReport timestamp in milliseconds node_nameSTRINGDevice name group_nameSTRINGCollection group name valuesSTRUCTCollection of measurement values values.currentFLOATCurrent values.voltageBIGINTInteger voltage values.phaseFLOATPhase -
Save the stream and confirm that its schema includes all tags to be written.
An explicit schema preserves voltage as an integer instead of treating schemaless JSON numbers as floating-point values. BIGINT is an eKuiper integer type and does not specify the Modbus register width. Enable Shared to let multiple rules reuse the same source.
5. Create a Data Processing Rule
-
Go to Data Processing → Rules → Create Rule and set the rule ID to
meters_to_tdengine. -
Enter the following statement in the SQL editor.
SELECT values.current AS current,
       values.voltage AS voltage,
       values.phase AS phase,
       timestamp AS ets,
       node_name AS device,
       CASE WHEN node_name IN ("workshop01_meter01", "workshop01_meter02")
            THEN "1" ELSE "2" END AS group_id,
       CASE WHEN node_name IN ("workshop01_meter01", "workshop01_meter02")
            THEN "Factory01.Workshop01" ELSE "Factory01.Workshop02" END AS location
FROM meters_stream
WHERE group_name = "electrical_readings"
  AND node_name IN ("workshop01_meter01", "workshop01_meter02",
                    "workshop02_meter01", "workshop02_meter02")
This SQL selects reports from the four meters'
electrical_readingsgroups, extracts current, voltage, and phase, preserves the original timestamp and device name, and assigns the location and business group identifier by device name. The device name determines the subtable name; location and business group are written as TAGs. -
Click Add Action, select InfluxDB v1, and configure the write action in the next step.
All four devices share one rule. When adding or replacing devices of the same type, update the northbound application subscriptions, device filter, and location and business group mappings in SQL. A separate rule for each device is unnecessary.
If collection reports contain metadata such as location and business group identifiers, declare those fields in the stream and select them directly in SQL as TAG values. This reduces per-device mapping configuration. This example assigns these attributes with CASE expressions.
6. Configure the InfluxDB v1 Action
The following JSON is a complete InfluxDB v1 action configuration and corresponds to the interface settings below. Replace the address, username, and password.
{
  "addr": "http://adapter-host:6041/influxdb/v1?table_name_key=tbname",
  "username": "<tdengine_username>",
  "password": "<tdengine_password>",
  "database": "neuron_meters_demo",
  "measurement": "meters",
  "precision": "ms",
  "tsFieldName": "ets",
  "fields": [
    "current",
    "voltage",
    "phase"
  ],
  "tags": {
    "tbname": "{{.device}}",
    "device": "{{.device}}",
    "group_id": "{{.group_id}}",
    "location": "{{.location}}"
  },
  "sendSingle": true,
  "batchSize": 1000,
  "lingerInterval": 100,
  "enableCache": true,
  "memoryCacheThreshold": 1024,
  "bufferPageSize": 256,
  "maxDiskCache": 102400,
  "resendInterval": 500
}
-
Enter the following settings under Connection, replacing the address and account details with actual values.
Setting Value Address ( addr)http://adapter-host:6041/influxdb/v1?table_name_key=tbnameUsername ( username)Dedicated TDengine write account Password ( password)Password for that account Database ( database)neuron_meters_demoKeep
/influxdb/v1in the address. The client appends/pingor/writeand preserves the query parameters. Enter the username and password in separate fields. In production, use a dedicated write account and restrict access to configuration files, exported files, and management APIs. -
Configure the field and tag mappings under Data Processing.
Setting Value Precision ( precision)msMeasurement ( measurement)metersTimestamp Field ( tsFieldName)etsFields ( fields)current,voltage,phaseTag tbname{{.device}}Tag device{{.device}}Tag group_id{{.group_id}}Tag location{{.location}}table_name_key=tbnameusestbnameto name the subtable without storing it as a TAG.devicepreserves the device identity. Select only the three measurement columns infieldsto avoid writing helper fields such asetsas measurement columns.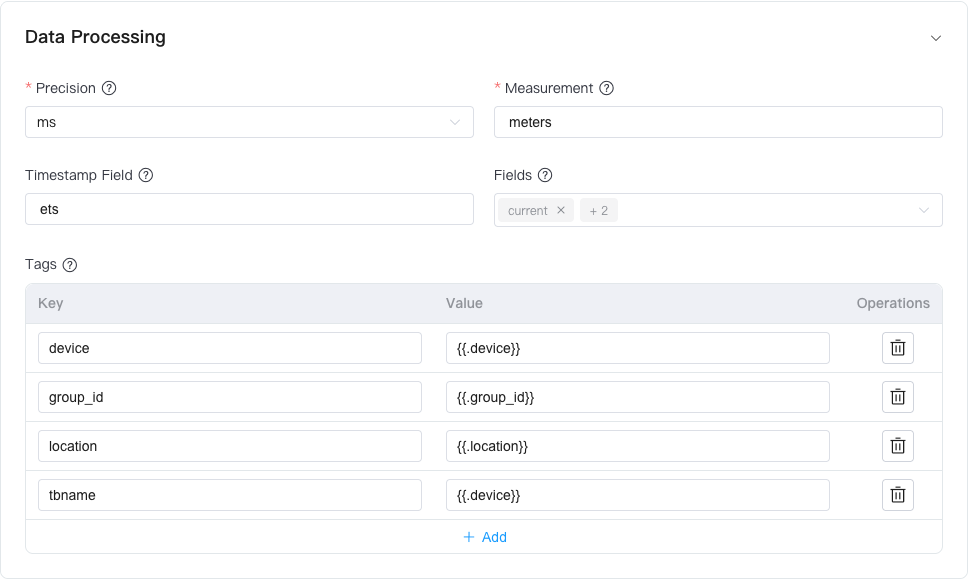
-
Expand Sink Properties, set Enable Cache (
enableCache) toTrue, and configure batching and caching as follows.Setting Value Purpose Batch size ( batchSize)1000Sends when the batch size is reached Linger Interval ( lingerInterval)100Waits this many milliseconds for an incomplete batch Enable cache ( enableCache)TrueEnables the sink cache Memory cache threshold ( memoryCacheThreshold)1024Sets the in-memory message threshold Buffer page size ( bufferPageSize)256Sets the number of messages per disk page Maximum disk cache ( maxDiskCache)102400Sets the disk cache message limit Resend interval ( resendInterval)500Sets the resend interval in milliseconds A batch is sent when either
batchSizeis reached orlingerIntervalexpires, whichever occurs first. Low traffic does not have to fill a batch of 1,000 rows. A cached message can contain a batch of rows, so message counts do not directly indicate row counts or the supported outage duration. Refer to the documentation for your eKuiper version for parameter details.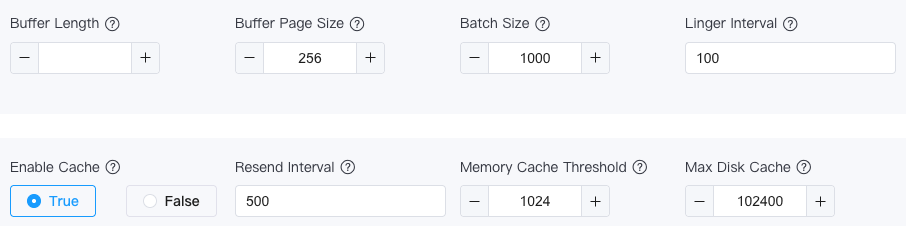
-
Submit the action, then save and start the rule.
The NeuronEX interface sets sendSingle=true by default to evaluate dynamic tags for each row. It does not send a separate HTTP request for each row. Retain this parameter when configuring a rule through JSON. Data is still sent in batches according to the settings above, and each device writes to its own subtable. Actual latency also includes queueing and network calls.
Writes to the same subtable with the same millisecond timestamp overwrite existing data. Use globally unique subtable names and preserve report timestamps. Explicitly update subtable TAGs when attributes such as location change.
Verify the Results
Regardless of the onboarding method, confirm ingestion through query results — a running rule or a successful ping does not confirm that data is being written. The following SQL uses the database and table names from the manual onboarding example. For install-time onboarding, use neuron_demo (demo) or neuron (real devices) as the database and the collection group name as the supertable name. For one-click onboarding, use your target database and mapped supertable names.
-
In a TDengine SQL client, check the automatically generated schema and device tags.
DESCRIBE neuron_meters_demo.meters;

SELECT DISTINCT TBNAME, device, group_id, location
FROM neuron_meters_demo.meters;
There should be four subtables with field types and tags matching the example data model.
-
Query the latest data and compare it with Data Collection → Data Monitoring. Replace the subtable name to check all four devices.
SELECT _ts, current, voltage, phase
FROM neuron_meters_demo.workshop01_meter01
ORDER BY _ts DESC LIMIT 5; -
Repeat the following query a few seconds apart to confirm that the row count increases in all four subtables.
SELECT TBNAME, COUNT(*)
FROM neuron_meters_demo.meters PARTITION BY TBNAME;
View Monitoring
View rule runtime metrics in taosExplorer without logging in to NeuronEX. Go to Data In → Data Collection Agents → Neuron, open the integration record, and check the Monitoring Information area. The page refreshes every 5 seconds while open and stops requesting when closed.
| Metric | Normal status or action |
|---|---|
| Rule status | Running; if stopped, check whether NeuronEX restarted, the rule was stopped manually, or a trial rule reached its runtime limit |
| Sink connection | Connected; if disconnected, check the network from NeuronEX to taosAdapter and the TDengine service |
| Collected rows, sent batches | Continue to increase; sent batches are eKuiper batch counts, not database row counts |
| Cache | Can fluctuate briefly but should fall back; if the backlog keeps growing, see Store and Forward |
| Exceptions, latest exception | Normally 0; if nonzero, inspect the latest exception and check data transformation, credentials, or network |
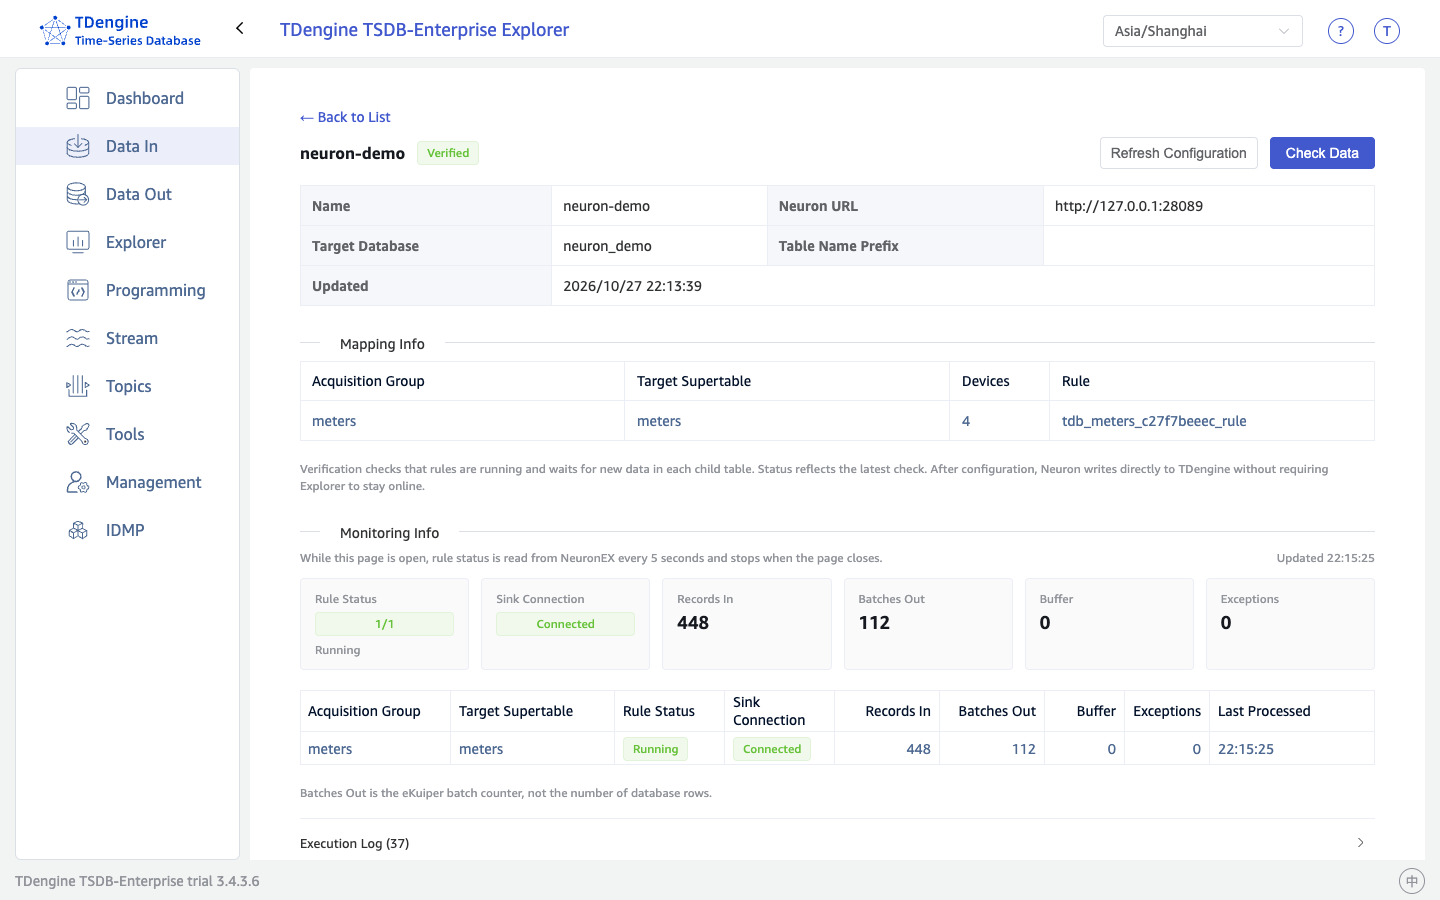
Neuron monitoring information in taosExplorer
A healthy sink connection and a running rule do not replace ingestion verification; use Verify the Results to confirm that data is written to TDengine. To view per-stage details, go to Data Processing → Rules in NeuronEX and click More → Statistics.
Display Data in IDMP (Optional)
In IDMP, configure a TDengine TSDB connection under Admin Console → Connections. For that connection, select More → Easy Import, then select neuron_meters_demo.meters.
Set the device tag as a path with path start level 0 and expression ${device}; set the location tag as a path with path start level 1 and expression ${location}. Import group_id as a static attribute. location is split at periods into factory and workshop levels, and device (the subtable name) becomes the leaf meter element.
After import, open the Element Explorer to view the following hierarchy. Select a meter to view its current, voltage, and phase measurement attributes.
Factory01
├── Workshop01
│   ├── workshop01_meter01
│   └── workshop01_meter02
└── Workshop02
    ├── workshop02_meter01
    └── workshop02_meter02
For detailed import instructions, see Build Data Models from TDengine TSDB. This ingestion example does not include unit information. To add units or configure conversions, see Units of Measure.
Store and Forward
The InfluxDB v1 sink in eKuiper provides buffering and forwarding for this integration. When a downstream service is temporarily unavailable, the sink caches data if capacity is available and the error is retryable. After connectivity recovers, it resends data with the original subtable names and report timestamps. Rules created by install-time and one-click onboarding already have the cache enabled (batching at 1,000 rows or 100 ms) and need no additional configuration.
To use this feature:
- Confirm that eKuiper includes the Influx v1 retry fix in PR #4201. Without it, resending might fail. Before deployment, provide EMQX with the NeuronEX and bundled eKuiper versions and confirm that the fix is included.
- For manual onboarding, under Data Processing → Rules, edit the rule's InfluxDB v1 action. Expand Sink Properties, set Enable Cache (
enableCache) toTrue, and configure capacity and the resend interval. See the parameter table and screenshot in Configure the InfluxDB v1 Action. Mount the eKuiper data directory on persistent storage. - Monitor disk space, cache length, and exceptions. If the backlog keeps growing, adjust the collection interval, batching settings, or collection group assignments.
A build containing the fix passed connection outage and recovery testing, and all test data was resent successfully. Authentication, permission, or schema errors can also be retried continuously and block subsequent data; correct these errors manually. Errors during data conversion or Influx point construction do not necessarily trigger retries.
A process crash or host failure can lose data held in memory or in transit. Data can also be lost if cache capacity is exhausted.
For parameter details, see eKuiper Sink Cache and Sending Mechanism.
Encrypted Transport and High Availability (Optional)
For mTLS or taosAdapter failover, deploy Nginx or HAProxy as described in taosAdapter High Availability and change the Neuron sink address to the load balancer endpoint. A basic direct HTTP connection does not require this configuration. For one-click onboarding, enter the load balancer address as the TDengine Address in the wizard.
Neuron-Side Configuration
Neuron writes use the InfluxDB v1 path. Configure the load balancer as described in Nginx Load Balancing and Failover, including the location /influxdb/v1/ retry policy and health checks. Configure TLS/mTLS as described in TLS and mTLS. The example still uses ingest.example.com:8443 as the load balancer endpoint.
In the rule's InfluxDB v1 action, set the address to https://ingest.example.com:8443/influxdb/v1?table_name_key=tbname. Under the action's Connection settings, upload the client certificate, private key, and server CA certificate. Set Skip Certification Verification to False. For file-based configuration, use the following parameters. Certificate paths must be readable by eKuiper; mount the certificates when using containers.
{
  "rootCaPath": "/etc/ekuiper/certs/server-ca.crt",
  "certificationPath": "/etc/ekuiper/certs/client.crt",
  "privateKeyPath": "/etc/ekuiper/certs/client.key",
  "insecureSkipVerify": false
}
Save the action and start the rule. Follow Verify the Results to confirm that data continues to arrive. Disable temporary plaintext endpoints in production.
For HTTPS with server authentication only, disable client-certificate verification as described in TLS and mTLS and keep CA verification on the eKuiper side. Retries preserve the subtable name, timestamp, and measurement values so that writes with the same key handle duplicates; failed batches rely on the sink cache for resending. See Health Check and Retry Semantics for the general retry and non_idempotent behavior.
Configure High Availability at Each Layer
| Layer | Deployment requirement | Considerations |
|---|---|---|
| nginx | A pair of hosts with a Keepalived VIP, or an existing highly available load balancer; the sink uses a shared domain | Synchronize configuration and certificates; the domain must match the certificate |
| taosAdapter | One instance on each of three nodes, connected to the same TDengine cluster | Multiple instances on one host do not protect against host failure |
| TDengine | Configure clustering and replication according to the version and license; see Deployment Management | The standalone database configuration in this example does not provide database high availability |
| NeuronEX | Synchronize configuration according to the official primary/backup guide; normally only the primary collects data | Collection can pause during failover; current Modbus register values generally cannot recover historical readings |
| Edge-to-center network | Enable the sink cache and monitor capacity | See Store and Forward for recovery limits |
Validate primary/backup and cluster failover for the actual deployment topology.
Performance Reference
Test Configuration
The following results are from an existing performance test and are provided for capacity planning. The test covered normal connectivity with caching and nginx mTLS enabled. The test versions below differ from the direct connection functional verification environment described earlier.
| Item | Configuration |
|---|---|
| Hardware | Intel Xeon E5-2696 v4, 22 physical cores, 44 logical cores, 64 GiB RAM, NVMe |
| Deployment | Ubuntu 24.04, Linux x86_64, all components running as native processes on one host |
| Neuron | Open-source version 2.15.0, custom build with a Modbus transaction ID rollover fix |
| eKuiper | 2.4.2+pr4201-perfcore test build with an Influx error classification fix |
| TDengine | Enterprise Edition 3.4.3.6; ms precision, VGROUPS 16, WAL_LEVEL 1, WAL_FSYNC_PERIOD 3000 |
| Collection | 16 drivers × 4 groups × 128 logical meters × 3 measurements, totaling 24,576 configured tags; 100ms interval |
| Northbound | 8 applications subscribe to separate collection groups; 8 groups per application, each application with its own source, rule, and output action |
| Batching and security | 100ms batch interval, batchSize=10000, about 1,024 rows per request on average; cache enabled, bufferLength=20000, disableBufferFullDiscard=true, nginx mTLS, CA verification |
The test read the simulator bundled with Neuron over Modbus, reusing registers across groups. The 8,192 logical meters do not represent 8,192 physical devices. Each row contains three collected values; tag values are excluded from measurement value throughput.
Reference Results
| Metric | Measured result |
|---|---|
| Net increase in database rows | 147,524,815 rows |
| Average ingestion throughput | 81,913.81 rows/s |
| Equivalent measurement value update throughput | 245,741.42 values/s |
| Throughput range across sampling intervals | 80,359.68–83,470.95 rows/s |
| Report-to-successful-response p99 | 1,171ms |
| Maximum latency using the same definition | 2,054.33ms |
| Sampled peak sink queue | 82 batches, later returning to zero; final queue length was zero |
Throughput is calculated from the net increase in database rows, with three collected values per row. Measurement value throughput is not the number of configured tags. The p99 is measured from the report timestamp to the successful taosAdapter response, at 1ms resolution. It includes batching wait time, queueing, and downstream calls, and excludes Modbus collection time.
After collection stopped and the cache drained, the rule's valid output row count, the row count represented by successful requests, the number of unique subtable name/timestamp combinations, and the database row count matched. Reconciliation excludes reports with missing values that the rule filtered out.
Neuron and eKuiper each used about 6.6 logical cores on average. Neuron resident memory was about 73MiB, eKuiper's sampled peak was about 275MiB, and nginx overhead was small. Neither resident memory nor the sink queue showed sustained growth.
These results support capacity planning and do not represent TDengine's write limit or a performance guarantee for official releases. Retest with actual devices, rules, field counts, networks, and hardware, and reserve capacity. To scale further, partition collection groups across multiple Neuron instances with corresponding eKuiper instances, allocate separate CPU resources, and use unique subtable names. Multi-instance scaling ratios have not been verified.
Troubleshooting
| Symptom | Checks and actions |
|---|---|
| No integration record appears in taosExplorer after install-time onboarding | Confirm the installation command succeeded. For same-host installation, check the local taosExplorer; for cross-host installation, check the taosExplorer at --tdengine-host. Review the installation output and taosExplorer logs |
| The status remains "Configuration Preserved; Verification Pending" after install-time onboarding | Confirm the four demo devices are running and connected; check whether Data Monitoring in NeuronEX shows data, and review taosExplorer logs |
| Forgot the NeuronEX administrator password | Run sudo cat /var/lib/apex/neuronex-admin-password to view the password generated during installation |
| Data stops after changing the NeuronEX password | Re-run the installation command and pass the new password with --neuron-password-file to update the credentials in taosExplorer |
| One-click onboarding reports "No acquisition groups with readable points were found" | Configure device collection in Neuron first; confirm devices are running and connected, with tag values visible in Data Monitoring |
| One-click onboarding fails with a subtable name conflict | The subtable name conflicts with an existing table in the database; set a Table Name Prefix for the integration to distinguish it, and confirm that same-named measurement columns have compatible types |
| Data stops being written after the TDengine password is changed | Click Refresh Configuration on the integration detail page to update the rules with the current login credentials |
| The detail page shows "Configuration Preserved; Verification Pending" | Confirm that Neuron is collecting and the rules are running in eKuiper, then click Check Data to verify again |
| Synchronization fails after deleting a device or collection group | The current version does not automatically clean up old rules. Delete the corresponding rule in eKuiper, then click Refresh Configuration and retry |
| Incorrect collected values | Check the unit ID, register addresses, byte order, and whether floating-point addresses overlap |
| A rule stops automatically after starting | Check whether the license includes data processing; a rule running under a test license can stop after 60 minutes |
| HTTPS connection fails | Check the CA, server certificate SAN, client certificate, and certificate paths inside the container |
| Cache length keeps increasing on the taosExplorer detail page | Adjust collection intervals, batching settings, or collection group assignments to prevent sustained sending rates below collection rates |
| Data is not resent despite caching being enabled | Confirm the version includes the retry fix described in Store and Forward, then check error classification, disk space, and cache capacity |
Appendix: Data Mapping and Collection Configuration Guidelines
Before onboarding, understand how Neuron objects map to TDengine objects and what kind of collection configuration onboards smoothly.
With install-time onboarding, the installer handles object mapping and table structure automatically, so you can skip the object mapping section. The device naming and grouping guidelines apply to all three methods; read them before configuring devices in NeuronEX.
Object Mapping
| Neuron object | TDengine object | Description |
|---|---|---|
Device (southbound node) node_name | Subtable | One subtable per device; the subtable carries a device tag recording the device name |
Collection group group_name | Supertable | One collection group maps to one supertable; devices in the group share the table schema |
Tag values.* | Measurement column | Each tag maps to one measurement column |
Report timestamp timestamp | Timestamp column _ts | Millisecond precision |
Install-time onboarding and one-click onboarding perform this mapping automatically and additionally attach fixed tags: device (device name), group_name (collection group name), protocol (the plugin protocol used by the device), and gateway (the Neuron gateway address, used to distinguish multiple gateways writing to the same database). The subtable name defaults to "prefix + device name"; when a device name cannot be written as-is or a device belongs to multiple collection groups, TDengine generates a name from the tag set. Manual onboarding lets you define tags and subtable naming yourself. Attributes such as location, unit, and business hierarchy are not part of collection configuration; install-time and one-click onboarding do not infer them — use manual onboarding to define them when needed.
Naming and Grouping Guidelines
The following guidelines apply to the collection configuration in Neuron itself, regardless of the onboarding method. Following them produces the clearest, most readable table structure:
- Device names are globally unique. Devices with the same name write to the same subtable, mixing their data. Device names are naturally unique within one Neuron instance; when multiple Neuron gateways write to the same database, device names may collide — set a distinct subtable name prefix for each gateway.
- Use well-behaved characters in device names. Letters, digits, underscores, hyphens, and Chinese characters are all fine, including names starting with a digit. Avoid periods
., quotes, backslashes, and control characters; otherwise the device name cannot be used directly as a subtable name and a generated name is used instead, which is less intuitive when troubleshooting. - Put each device in only one collection group. Subtable names are globally unique within a TDengine database and are not isolated by supertable, so a device that spans groups cannot reuse its device name as the subtable name in each group.
- Keep device schemas consistent within a collection group. A collection group maps to a supertable, so devices in one group should have identical tag names and types; otherwise same-named columns conflict. Put devices with different schemas in different groups.
- Use valid identifiers for group names. A group name with lowercase letters, digits, and underscores, not starting with a digit and at most 64 characters long, can be used directly as the supertable name.
- Use well-behaved characters in tag names. Tag names are normalized when converted to column names (lowercased, special characters replaced with underscores, a prefix added when starting with a digit); reserved names such as
ts,_ts,ets,device, andgroup_nameare renamed automatically. Tag names containing backticks or backslashes cannot be converted to column names.
Type Mapping
Neuron tag types map to TDengine column types as follows. Install-time onboarding and one-click onboarding apply this table automatically and create tables on first write; for manual onboarding, use this table as a reference when writing your own rules:
| Neuron tag type | TDengine column type | Description |
|---|---|---|
INT8/INT16/INT32/INT64, UINT8/UINT16/UINT32, BIT, WORD/DWORD/LWORD | BIGINT | |
UINT64 | BIGINT | Values outside the signed 64-bit range are truncated (known limitation) |
FLOAT, DOUBLE | DOUBLE | |
BOOL | BOOL | |
STRING | NCHAR | |
BYTES | NCHAR | Written as base64 text |
ARRAY_* | NCHAR | Written as JSON array text |
| Integer tags with a scale factor | DOUBLE | Converted to a floating-point value according to the scale |